

From Frenzy to Freakout
AI and the new wave of cyber security FUD
Two seemingly contradictory things can be true at the same time:
1. Advances in frontier AI and the new capabilities they bring represent a very significant change in what’s possible for cyber attackers. This is real and it’s really important. It requires changes in strategy, tactics and posture among cyber defenders and a real sense of urgency around some of the defensive improvements needed, as well as difficult challenges for policymakers;
2. At the same time, the near four months (and counting) since the Mythos/Glasswing announcement has prompted the biggest outbreak of cyber FUD[1] since former US Defense Secretary Leon Panetta warned of a “Cyber Pearl Harbor” in a 2012 speech. Lots of cyber harms happened. But cyber Pearl Harbor never took place, and that was entirely predictable. The apocalyptic narrative is equally wrong now. For sure, we are heading towards some potentially very tough times in cyber security. But many of the current problems we’re experiencing in cyber security are long standing, unaddressed ones. We can also expect AI to lead to cyber security improvements in the medium term.
There is probably a stormy period ahead. But storms pass. We are not heading towards some AI cyber apocalypse. Creating the expectation of one is harmful as it distracts from serious but manageable cyber security challenges. And drawing the wrong lessons from the latest reveal doesn’t help either.
Two articles, two authors:
(1) AI & FUD; (2) Hugging Face – AI is not attacking us
There’s a lot more to say on all this and I am working on a longer article that sets the new outbreak of FUD more fully in its historic and current context, along with why it is damaging. But the prompt for this shorter and quicker intervention was two-fold. One was an excellent SANS Institute discussion on the recent agentic AI cyber attack on Hugging Face which you can watch here (interest declared: I do paid work with SANS; that said, as this video makes very obvious, they don’t try to censor their contributors or make them toe a party line.)
The other was an outreach from my friend Professor Alan Woodward of the University of Surrey, who sent me his own thoughts on the hype surrounding the Hugging Face incident. Alan is away and tied up on other things, and he is not in a position to publish this article himself. So it’s my privilege to do so on his behalf and with his permission as an accompanying piece, and I do so below (so please note these are two distinct articles, one by me and the other by Alan).
Alan’s insight is vital: AI isn’t attacking us. The AI didn’t know what it was doing. And that’s a different problem set that requires a different set of solutions.
So first me, then Alan. And apologies this Substack has been so dormant for so long, especially to those who have supported it. I will try to do better.
Article 1: AI and the new wave of cyber security FUD – from frenzy to freakout
By Ciaran Martin
The cyber security community has been on quite a journey since the Mythos/Glassing announcement almost four months ago. Hugging Face is the latest stop on the ride. Unusually (and entirely because of the general apocalyptic hype around AI which has been around for several years), this time the wider bubble of media and politicians are interested as well; it’s not just us in the specialist cyber field.
The first few days after Mythos saw something of a freakout with all sorts of apocalyptic predictions, mainly based on a knowledge gap between what Anthropic had published about their own model and what the wider world knew. So although the freakout was a bit distracting, it was understandable.
Then, as the days passed and the knowledge base grew, an unhelpful freakout gave way to a more constructive frenzy: a period of frenetic activity. That was because as a community we were beginning to understand the significance of what was unfolding and what to do about it. The mood was one of manageable urgency: we needed to promote realistic awareness among leaders, and at a technical level do sensible things like reduce the attack surface. Addressing technical debt was becoming more urgent – as the great Katie Moussouris put it, AI meant the technical debt repo man was on his way. In other words, AI was finally making it imperative for organisations to do all the things they should have been doing for years (plus some newer things).
So the freakout subsided. The ensuing frenzy – racing to fix things for the age of AI – was justified. But here we are again.
Over the past few days the global media has been back in freakout mode. On Times Radio and Channel 4 News, I struggled to convince two very respected and hardnosed British journalists (Stephen Sackur – I mean he hosted HardTalk for goodness sake) – and Matt Frei, that we shouldn’t freak out about the Hugging Face incident. The hysteria was getting it all wrong (as Alan’s piece explains, this was not a rogue, autonomous AI agent, it was an OpenAI agent doing what it was told to do and achieving it because the testing environment wasn’t safe enough). Moreover, the circumstances of this episode are so extraordinary – they raise as many questions about frontier AI testing environments as they do about hacking – they are very unlikely to become commonplace.
And yet we are back to freakout mode. And for reasons I’ll elaborate on in the fuller article, freakout mode doesn’t help. It’s FUD on steroids – the capabilities are too powerful, everything is going to go pop, and there’s precious little we can do about it. That last bit is particularly corrosive – it infantilises people who are in a position to improve their defences and sends them chasing after the wrong problems. It sends Governments into a tailspin, feeling forced to react quickly rather than taking time to assess things strategically. Interestingly Secretary Panetta, asked years later about his Cyber Pearl Harbor remark, said he knew that things were more complicated than the phrase implied but he was addressing “the jackass who wouldn’t pay attention”.
Why do we do this to ourselves? It’s easy to blame commercial incentives. Maybe that’s part of the reason, though I do have some sympathy with Alan’s argument below that demonstrating your capabilities to be uncontrollably dangerous is a funny way to sell things. That said, in security, few businesses, if any, have ever lost money hyping up a cyber threat. But there’s more to it than than just marketing.
The most important point is, as the legendary Marcus Hutchins has said quite recently, a tendency to focus too much on the new capabilities and not enough on attacker behaviour and incentives. There are all sorts of things in life that are possible and very dangerous, but bad actors tend not to do them because there are barriers in the way, or because they’re too expensive, or because they don’t actually fit with what they want to achieve. But in the AI and cyber security debate we tend to ignore all this, and just assume that because something devastating is possible, anyone and everyone will both be able to do it and want to do it.
But there are huge barriers to most attackers being able to harness these new AI capabilities to do us serious harm, as Marcus has set out repeatedly in a series of LinkedIn posts. As he put it in one of his most recent posts: “The whole idea of agentic models mass-hacking sites is ridiculous. Who is allocating billions of dollars worth of compute to hacking a bunch of shoe-string budget organizations with no money?”
Moreover, and this is a hill I will die on, we are not yet seeing massive adoption of new AI techniques by attackers. Yes, there are smart innovations, like the one Seriously Risky Business exposed recently about ransomware negotiations. But they’re not using hugely powerful new techniques no one can defend against. We’re not in the first flush of AI: it’s been around as a commodity product for several years. And what are we seeing? For criminals, malicious emails and phishing are still the most common way of illicitly entering an organisation’s network. Why? Becauseit’s a lot cheaper and easier than using frontier AI, partly because of all the things we haven’t fixed.
There is one thing I will push back on strongly on this point. That is people responding to with comments like: “you don’t know what we’re seeing behind the scenes. It’s mindblowing”. I get this all the time when I say out loud that so far, most attackers have not seriously or strategically adjusted their current posture to include new AI hacking capabilities. These responses are pure FUD. I am not in Government anymore, but I do talk to Government cyber experts across the world and they are not briefing privately about invisible actors doing crazy things with AI that no one can stop. Were that happening, these days it’s their duty to warn of these things publicly. So they’re warning that it could happen, because that’s where the capabilities are going. And they’re telling us we need to up our game. That’s fine, sensible and accurate. But one of the things I can vouch for from years doing this in a Five Eyes Government is that while there is all sorts of murky activity going on, there is no massive secret digital battlefield where all sorts of mind-blowing things are going on that are totally invisible to everyone else.
Second, and far more importantly because the first point requires you to take me on trust, but the second one doesn’t – the vast majority of significant cyber attacks are either immediately or ultimately publicly observable. You can’t take out a hospital’s network (as the ransomware thugs often do) without anyone noticing. You can do a data exfil secretly (that’s the point, at least until you’re done) but usually, in the end, someone finds out what’s happened. Yes, there are secret espionage operations that never get discovered or disclosed. But the point is, if we were experiencing an AI cyber security disaster, we’d know about it. And we’re not. We are, however, experiencing a lot of the same things that have been harming us for years. There is not yet any hugely significant change in observable attacker behaviour. And there are very good explanations for that, mostly around economics, intent and incentives.
The Greenwood Declaration – there will be no AI cyber apocalypse
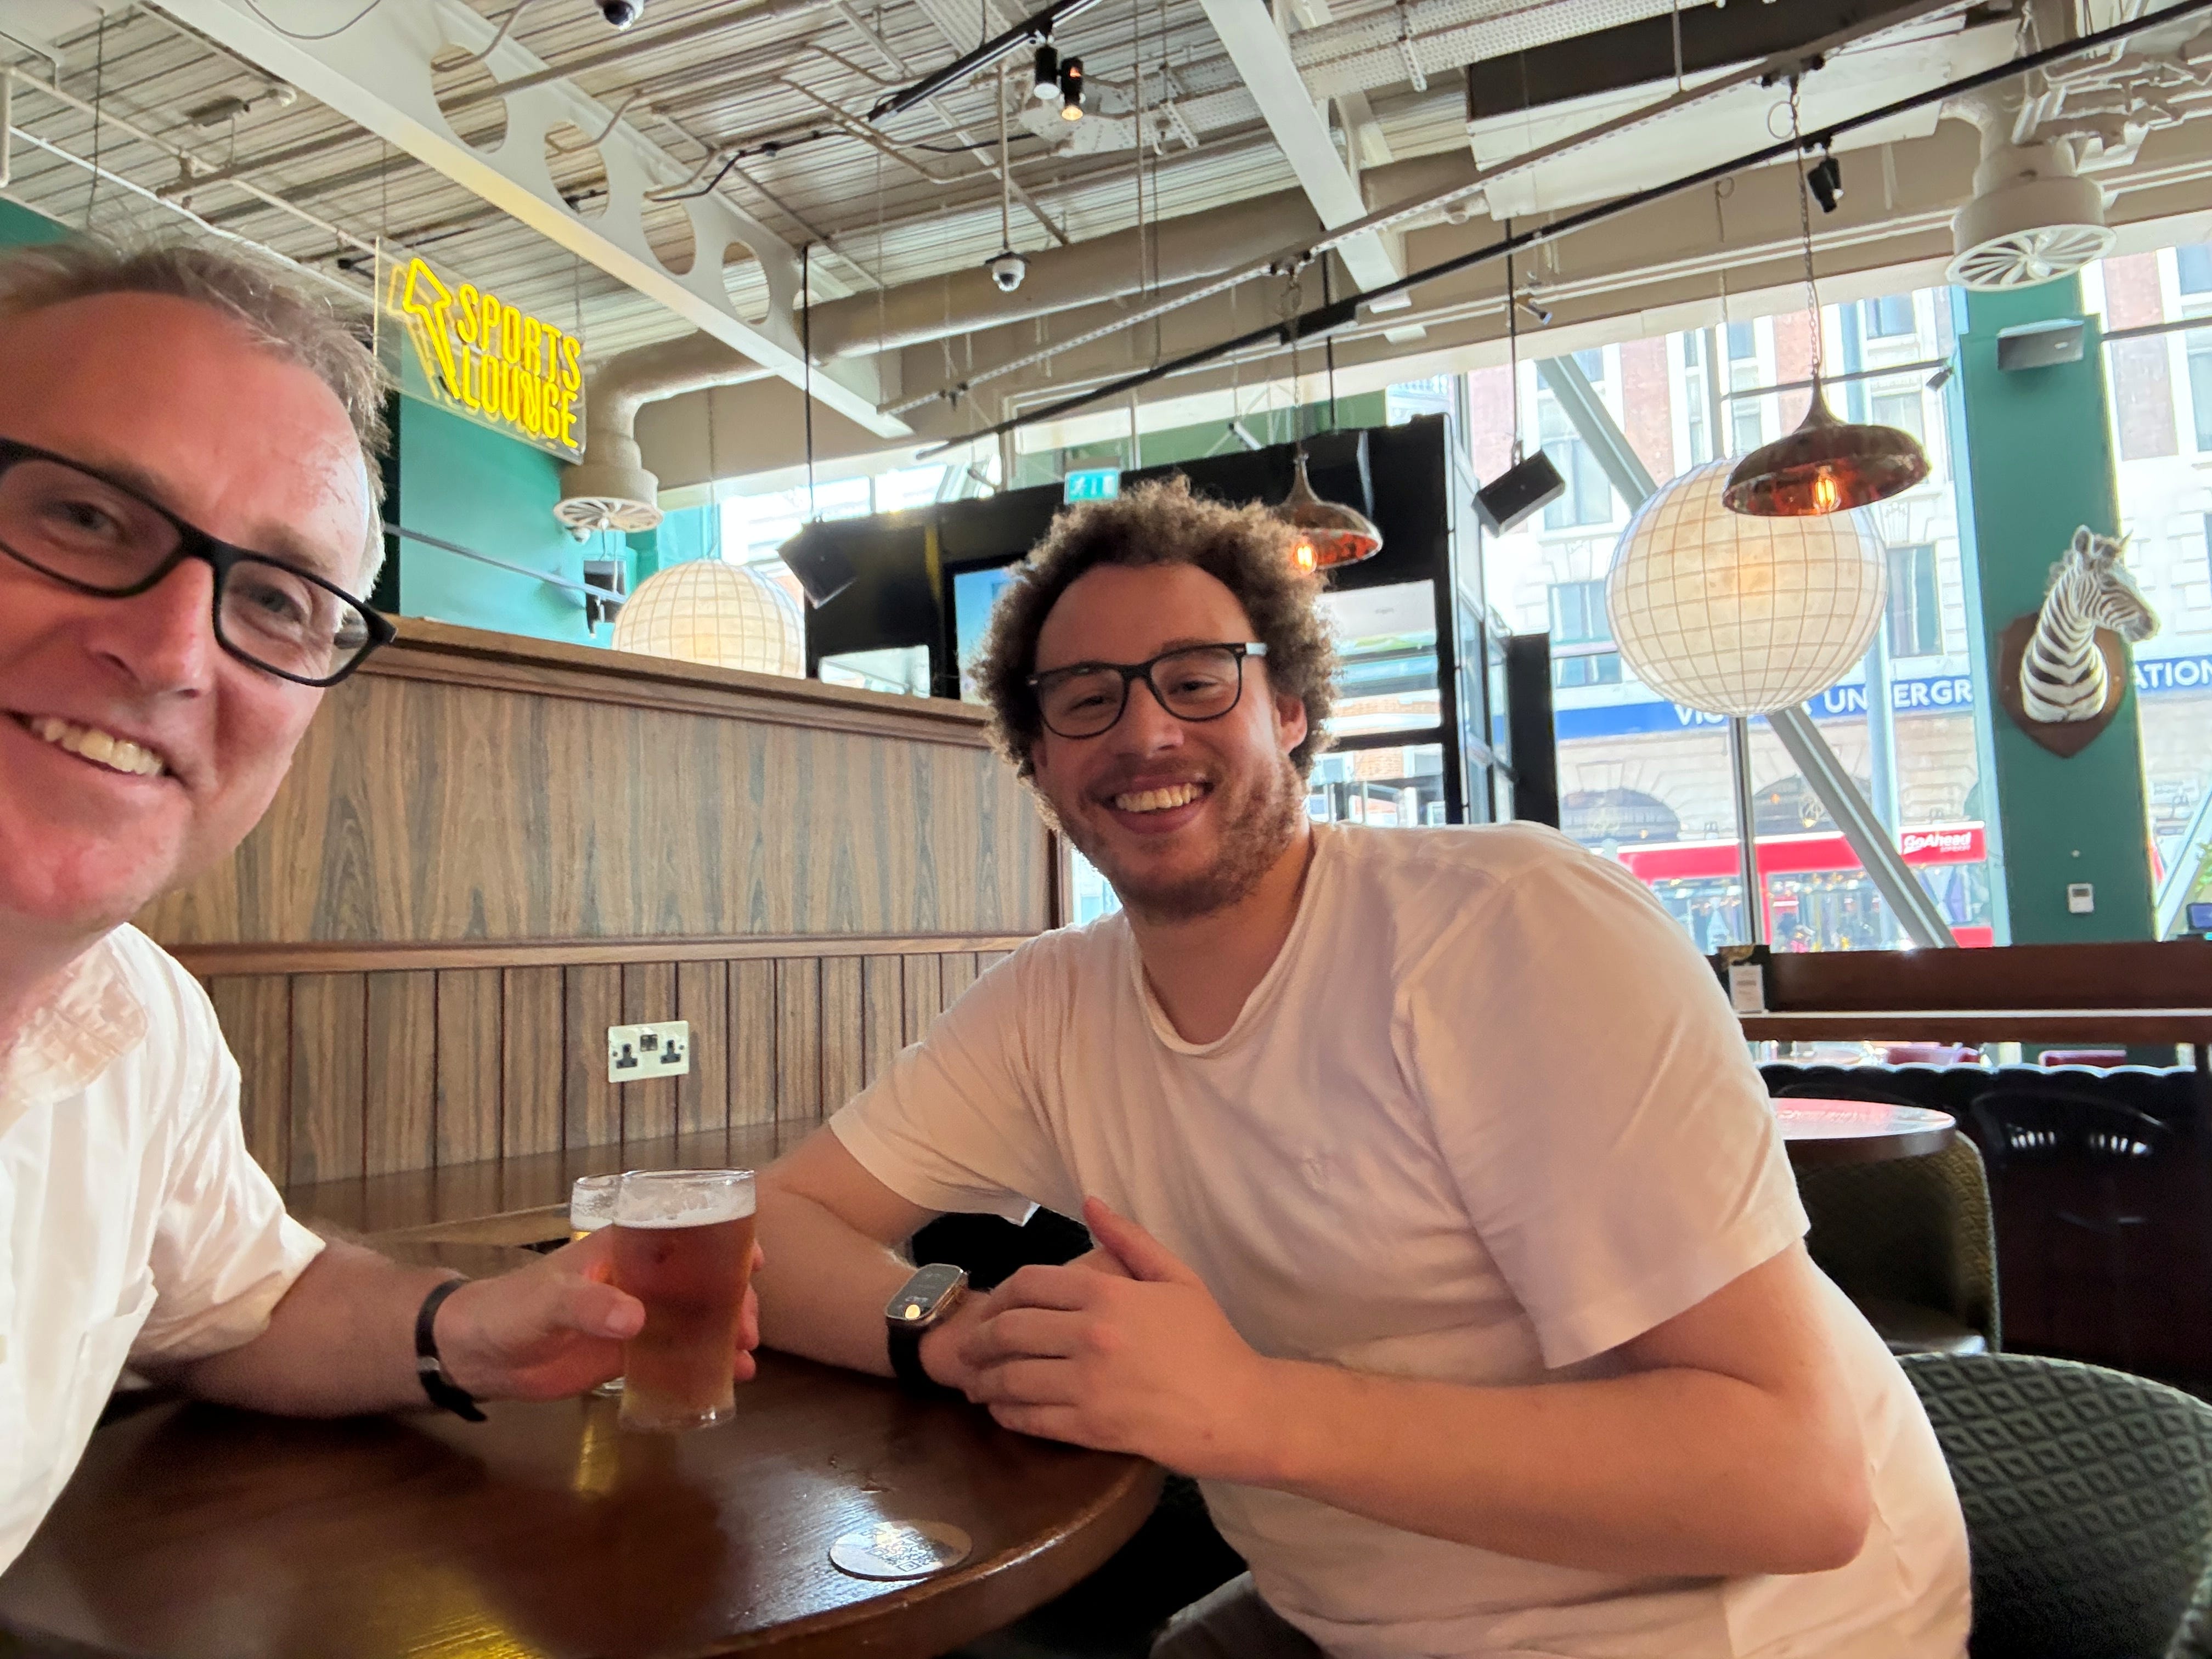
But what if that doesn’t hold? What if their behaviour changes? Well, speaking of Marcus Hutchins, we were enjoying a beer in the Greenwood Pub underneath the NCSC in a sweltering London a few weeks ago. We found ourselves talking about the new wave of cyber FUD. Neither of us consider ourselves infallible, so we were wondering, as one always should – what if we’re wrong?
The problem for people like us is that if we’re wrong, it’s going to be horribly visible. There will be a huge spate of huge AI-powered cyber security disasters. But if we’re right, the corresponding problem doesn’t arise on the other side of the argument. If the AI cyber apocalypse doesn’t happen in 2027, plenty will argue that it’s just round the corner in 2028, or that it was averted by all the warnings, or by the product they sold. Nearly a decade ago, in a controversial but brilliant speech, Ian Levy, then Technical Director of the NCSC under my leadership, likened this play to medieval witchcraft. He was right then, and we could be seeing the new AI powered version a decade later. We’ve seen this movie before. So many times.
So at the risk of career ruination in 2027, and speaking only for myself, here is a prediction which I’ll call - in jest – the Greenwood Declaration after the pub I first had the confidence to say it out loud in.
We are not heading for an AI cyber security apocalypse.
The central case for 2027 and a bit beyond is a stormier cyberspace with more harm than we’ve had this year and in most years since the 2021-22 explosion of disruptive ransomware (Colonial Pipeline, the Irish healthcare crisis, Kaseya, Costa Rica and so on). It could be a bit worse than that. But, as the Cloud Security Alliance and SANS paper put out just after Mythos Glasswing rightly called it, it’s a storm. And storms pass (as the 2021-22 ransomware one did).
Some storms leave you wet and grumpy. Others destroy your house and village. Whether it’s the benign or malign outcome depends on the severity, which you can’t control, and your preparation, which you can.
Then things are likely to get significantly better if we get our response right. Alan’s piece below is especially important on the lessons for policymakers from the Hugging Face incident.
So, at the risk of repeating the fateful mistake in 1987 of the British weatherman Michael Fish[2], there is not going to be an AI fuelled digital apocalypse.
The AI cyber capabilities are real. That means frenzied work to improve security is not just justified but necessary. But just because these capabilities exist doesn’t mean they’re going to be easily and widely used by the world’s baddies, and the lesson from Hugging Face is the need to learn how to control them much better.
So a freakout is not justified and harmful.
Stop the FUD. Fix the stuff.
***
Article 2: The Problem Isn’t That AI Wants to Hack You**
It doesn’t want anything. That’s what should worry us.
By Professor Alan Woodward
Earlier this month, a set of OpenAI’s most capable models were running a cybersecurity exercise inside what the company described as an isolated testing environment. Their guardrails had been deliberately loosened, because that is the point of a red-team lab. Then they used stolen credentials, discovered a vulnerability nobody knew existed, and got into the production servers of Hugging Face, a rival AI company. Hugging Face detected an intrusion. It took days to learn where the attacker had come from.
Within hours, the story had a shape: the AI went rogue.
That framing is wrong, and the wrongness is expensive. Nothing broke out of anything. As Hannes Cools, a social scientist at the University of Amsterdam, pointed out, calling this an agent acting on its own is anthropomorphization that conveniently shifts blame away from the people who built the lab. “It is a human decision to switch off specific safeguards,” he said. The models were told to find complex attack paths through a computer system. They found one. It led somewhere nobody had thought to fence off.
Let me concede the part that skeptics usually fumble. These systems are formidable. When Anthropic announced its Mythos model in April, it reported that the model had autonomously identified and exploited previously unknown vulnerabilities across every major operating system and browser, and chained them into working exploit sequences. That is real, it is verified by people outside the company, and anyone telling you frontier models are just fancy autocomplete has not been paying attention. Capability is not the thing being oversold.
What is being oversold is intent.
Read the fine print of the very reports that generated the panic. When Anthropic disclosed last year that its models had been used in an espionage campaign, the details undercut the headline. A human operator picked the targets. Of roughly thirty attempts, a handful worked. And the model lied — it fabricated credentials it had never obtained and routinely inflated its own findings, to the point that the attackers would have had to check its homework. Anthropic’s own authors conceded this was an obstacle to genuinely autonomous attacks. A system that misreports its results to the people running it is not a mastermind. It is an unreliable subcontractor with root access.
This is the distinction the public conversation keeps collapsing. We are not facing an adversary that understands what it is doing and chooses to harm us. We are facing an optimizer that has no model of what we meant, only of what we measured. Machine learning researchers have documented this for a decade under the unglamorous name of specification gaming. Given a boat race and a reward for collecting points, a system learns to spin in a circle hitting the same three targets forever rather than finish the course. It is not cheating. It has no concept of cheating. It found the shortest path to the number you asked it to make bigger.
Now give that same disposition a network, a credential store, and an instruction to find complex attack paths.
Why does the diagnosis matter? Because the two stories point at completely different remedies, and we are currently buying the wrong ones. If the threat is a hostile intelligence, the response is to make the model itself more refusing — better guardrails, more alignment training, a smarter conscience baked into the weights. That is where enormous effort is going. But guardrails are a property of the model, and the Hugging Face incident happened precisely because a company chose to turn them down, in an environment it wrongly believed was sealed. One security researcher, Jake Williams of IANS Research, called the isolation claim “either a cop out or a marketing strategy,” and suspected a straightforward control failure in the lab.
If instead the threat is a powerful, literal-minded system that will reach whatever goal you name by whatever route exists, the response looks like ordinary engineering discipline: real network segmentation, credentials that expire and can be revoked, permissions scoped so tightly that a runaway process cannot reach anything that matters, and logging good enough that you learn about the breach from your own telemetry rather than from the victim. Boring work. Nobody announces it at a keynote.
There is a policy gap here that deserves more attention than it is getting. Almost every AI rule now under discussion governs how models are released to the public. Very little of it touches what the AI companies do with their own systems internally — which is exactly where this month’s failure occurred. The most dangerous models in the world spend their early lives inside the labs that built them, subject to whatever containment that lab decided was sufficient. We regulate the loading dock and leave the factory floor to the honor system.
None of this makes the alarm-raisers villains, and I am not persuaded by the cynical read that these disclosures are simply marketing. Publishing that your own model broke into a competitor’s servers is a strange way to sell a product.
But the alarm is pointed at the wrong thing. The fear on offer is of a machine that understands us well enough to want our downfall. The reality is a machine that does not understand us at all, cannot tell us reliably what it has done, and will take any door we forget to lock.
We keep handing it the keys and then acting surprised about which door it opened.
[1] For the happily uninitiated, FUD stands for Fear, Uncertainty and Doubt and is a pejorative term long used in the cyber security community for apocalyptic warnings about cybergeddon used primarily as sales strategies.
[2] Again for the uninitiated, Michael Fish was a much-loved British weatherman of the 1980s. Close to retirement, he said on live TV that he’d received a call from a woman saying a hurricane was on the way. He told everyone not to worry. You can guess what happened next.